
Table of Contents
A growing class of AI tools no longer measures people directly. Instead, these systems predict human behavior from the content itself. Rather than tracking a real person’s gaze or facial response, they estimate what that response is likely to be.
This shift can be incredibly useful. It makes testing faster, cheaper, and easier to scale. But it also changes where trust comes from. When there is no real participant in the process, a model has only one connection to reality: the human-labeled data it learned from.
As predictive AI spreads, the need for large, diverse, high-quality human datasets does not disappear. In many cases, it becomes even more important. The organizations that own the best ground truth data may hold the biggest long-term advantage.
Prediction Is Replacing Measurement
For most of its history, behavioral research relied on measuring real people. Researchers recruited participants, recorded their behavior, and analyzed the results across a sample.
Today, many AI systems work differently. Instead of measuring a person, they predict what a person is likely to do.
You can upload an advertisement and receive a forecast of where attention will go. Some systems estimate audience engagement without showing the content to a single participant.
Similar approaches now exist for eye tracking, facial responses, and other forms of behavior.
The appeal is obvious. A study that once took weeks can now take minutes. Hundreds of creative concepts can be screened before launching a single research project.
But prediction and measurement are not the same thing. When you stop collecting new data, the quality of the prediction depends almost entirely on the quality of the data used to train the model.
The General Rule: A Prediction Is Only as Good as Its Ground Truth
In machine learning, ground truth is the verified data a model learns from and is tested against. Put simply, it is the correct answer the model tries to match its “answers” to. In behavioral AI, ground truth comes from real people. It includes where people looked, how their faces moved, and how audiences responded.
When a system measures behavior, it stays connected to reality. A real person creates the data in real time. A predictive system works in a different way. It creates an answer from patterns found in past human data. There is no participant present to correct mistakes or show where the model is wrong.
Because of this, prediction depends heavily on ground truth. If the data is narrow, biased, outdated, or inaccurate, the prediction will reflect those weaknesses.
This leads to a simple rule. The less a model measures, the more it depends on the human data it was built on. The human never disappears from the process. The data simply moves further upstream..
Case 1: Predicted Attention
Predictive eye tracking estimates where people are likely to look without measuring any real viewers. That makes it fast, scalable, and inexpensive. But it also raises an important question: how does the model know where people will look?
The answer is that the AI learned from real eye-tracking data collected from real people. And the quality of its predictions depends on the quality of that data.
The field’s own benchmarks help show why. Popular datasets such as MIT300 and CAT2000 contain a few hundred to a few thousand images viewed by small groups of participants using lab-based eye trackers. A model can achieve impressive scores on these benchmarks and still struggle with a specific advertisement, product package, or website.
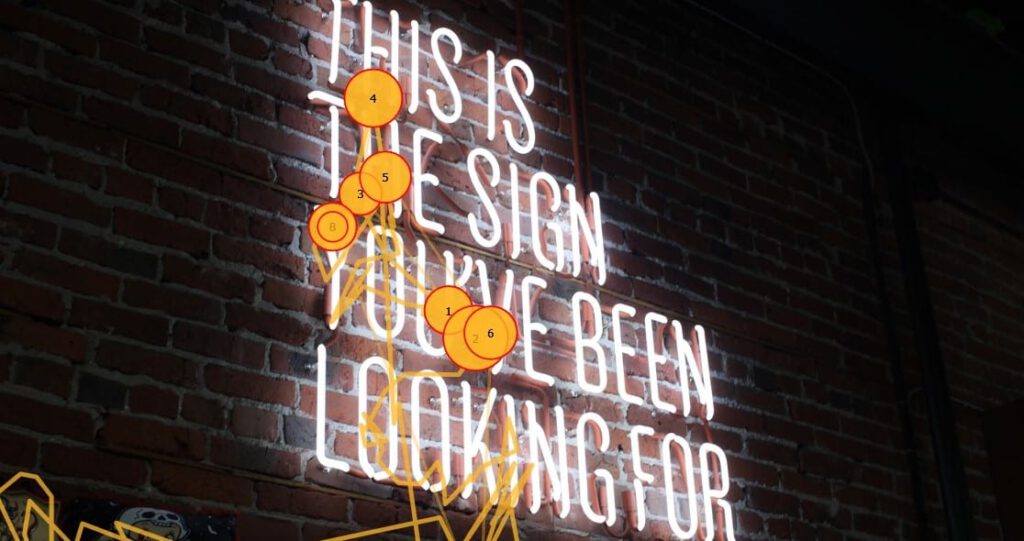
The reason for that is simple. The images in these datasets often look very different from the content businesses want to test. The tasks are different as well. Someone casually viewing a photograph is not doing the same thing as a shopper comparing products or a customer trying to complete a purchase.
The same pattern appears in the training data. SALICON, one of the most widely used saliency datasets, scaled to tens of thousands of images by using a mouse-based proxy for visual attention rather than traditional eye tracking. While mouse-derived attention data often correlates with gaze behavior, studies comparing mouse and eye-tracking data have shown that the choice of ground truth influences both the patterns captured in the dataset and the behavior of the models trained on it.
In other words, the field gained scale by using a proxy. That tradeoff made larger datasets possible, but it did not remove the need for real eye-tracking data. It simply moved that need further upstream.
The lesson is straightforward: better human ground truth leads to better predictions.
Case 2: predicted audience engagement, where the ground truth is the entire product
The same pattern appears even more clearly in audience engagement prediction.
Traditionally, engagement is measured by recruiting viewers, showing them content, and analyzing their facial responses moment by moment. Predictive engagement models attempt something different: they estimate that response directly from the content itself, allowing a creative to be screened before a single new participant is recruited.
The attraction is, again, obvious. So is the dependency on data. If the model never observes a new audience, everything it knows about audience behavior must come from the audiences it has already seen.
What makes this case sharp is that the ground truth and the moat are the same asset. The Affectiva corpus, built over more than a decade, spans more than 100,000 ads, over 18 million face recordings, and billions of video frames across roughly 90 countries. Crucially, its labels do not come from a cheap proxy.
They are grounded in the Facial Action Coding System (FACS), with trained human coders annotating specific facial muscle movements frame by frame, the painstaking, expert human work that underpins models regarded as a gold standard for automated facial coding.
A predictive engagement model trained on that archive is, in the most literal sense, a compression of an enormous amount of carefully labeled human response. Its credibility is the corpus.
This is the clearest possible illustration of the general law: the predictive model touches no new viewer, so everything it knows about human engagement, it knows because humans were measured and human experts labeled them. Scale, diversity, and labeling rigor are not nice-to-haves. They are the entire basis of trust.
What Good Ground Truth Looks Like
At this point, a natural question emerges: what separates a predictive model that deserves trust from one that simply sounds convincing?
The answer is not a single benchmark score or dataset size. Across different types of predictive AI, the same qualities appear again and again.
First, there is no substitute for real human data. Proxy measures can be useful, and sometimes they are necessary to achieve scale, but they are still only stand-ins. A model trained on mouse movements is not the same as a model trained on actual gaze data. A model trained on automatically generated labels is not the same as one trained on carefully coded human behavior. When it comes to validation, reality still matters most.
Scale matters too, but only when it comes with diversity. A dataset may contain millions of observations and still fail to represent the people a model is meant to predict. The goal is not just more data. The goal is broader data. Different cultures, age groups, contexts, and content types all help a model learn a wider range of human behavior.
The quality of the labels matters just as much as the quantity of the data. In many behavioral domains, labels are effectively the definition of what “correct” means. A FACS-based dataset is valuable not only because it is large, but because trained human coders spent years creating a consistent and reliable reference point.
The data should also resemble the environment where the model will be used. A model trained on generic images may perform well on benchmarks but struggle with advertisements, websites, product packaging, or other real-world content. Ground truth from the target domain is often more valuable than a much larger dataset from somewhere else.
The target itself must also be measurable. There is an important difference between predicting observable engagement and claiming to read someone’s private emotional state. The closer a model stays to things that can be observed, measured, and tested, the stronger its foundation becomes.
Finally, there is the problem of time. Human nature does not change overnight, but media environments do. Platforms evolve. Creative styles shift. New forms of content appear. A model trained on yesterday’s world can slowly drift away from today’s unless its ground truth is updated over time.
Taken together, these qualities point to a simple conclusion. The value of a predictive model depends on the quality of the human reality beneath it.
And that creates an interesting paradox. The more predictive AI spreads, the more important human ground truth becomes.
The More We Predict, the More We Need Human Truth
Take a step back, and you will see a clear pattern emerge. The more prediction replaces measurement, the more the entire system depends on human-collected and human-labeled data.
This dependency shows up in at least three places.
The first is training. Every new audience, platform, content type, or measurement approach eventually requires fresh human data. Models can generalize remarkably well, but they cannot generalize forever. A model trained on static images will only take you so far into video. A model trained in one cultural context will not automatically understand another. At some point, new human data has to enter the system.
The second is validation. A benchmark score may show that a model works somewhere, but it says little about whether it works for your audience or your content. Answering that question still requires measuring real people and comparing predictions against reality. Every serious validation effort creates new ground truth in the exact place where the model is meant to be used.
The third is in the areas where predictive systems still struggle. Cross-cultural differences. Task-driven attention. Dynamic content. The difficult relationship between observable behavior and internal emotional states. Many of the field’s biggest challenges can be traced back to ground truth that is limited, disputed, or incomplete. And many of the best solutions involve collecting richer and more representative human data.
For all the attention given to algorithms, this is the dependency that matters most. Automating the output does not remove the need for human truth. It increases its value.
The more successful predictive AI becomes, the more valuable high-quality ground truth becomes alongside it.
In a field built on prediction, the deepest, broadest, and most carefully labeled human datasets are not just a cost of doing business. They are the foundation the system rests on, and often the advantage that competitors cannot easily copy.
A Convenient Argument, but a Real Dependency
It is fair to point out that this argument is convenient for companies, such as iMotions, that collect, and label human behavioral data. It is convenient, but that does, however, not make it wrong.
The dependency is structural, not commercial. A predictive model that never measures a live participant has only one source of truth: the human data it was trained and tested on. There is nowhere else for that truth to come from.
If anything, critiques such as Barrett’s strengthen the argument. If human behavior varies more across cultures, contexts, and individuals than we once believed, then the quality of the underlying data becomes even more important.
The answer is not to have less ground truth. It is to have better ground truth. Broader. More diverse. More representative, and more carefully labeled.
The interests and the argument may point in the same direction. That does not prove the argument. But it does not weaken it either.
The dependency exists whether it is commercially convenient or not.
Prediction may automate measurement, but it cannot automate the reality that measurement came from.